Search

2 posts

Chunking for a Knowledge Base: One Markdown Convention, Chunked by Heading

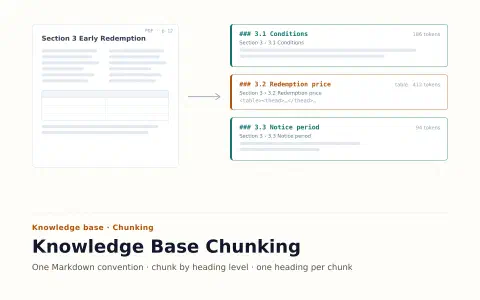
What the knowledge base maintains is Markdown: PDFs, web pages, manual material and Q&A all follow one convention, and the chunker reads only the Markdown heading tree and block structure. This post covers the convention, PDF transcription and checks, the heading-level chunking rules, and the retrieval evaluation showing why one heading per chunk works best.
  • AI
  • RAG
  • Chunking
  • Markdown
November 15, 2026 · 16 min · 3316 words · Sam Peng
Different sources become Markdown with a heading hierarchy, then are cut into chunks by heading

Building an Enterprise Knowledge Base: Content Model, Git Publishing and Hybrid Search

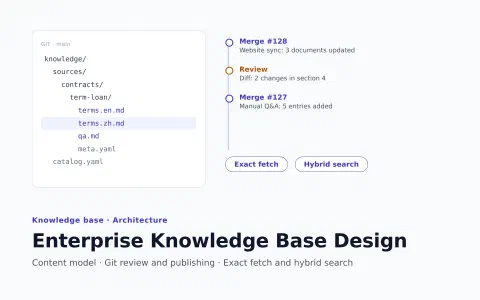
A knowledge base works like a library: categories, books and editions, tables of contents, passages, narrowing the context level by level to give the chat model accurate knowledge. Drawing on a bilingual project with about 1,800 documents, this post covers defining the content model first, using Git for review and publishing, keeping exact document fetch separate from hybrid search, and choosing retrieval methods with an evaluation set instead of intuition.

  • AI
  • RAG
  • Knowledge Base
  • Search
November 15, 2026 · 11 min · 2285 words · Sam Peng
Originals are converted into a Git-managed Markdown knowledge base, which serves both exact document fetch and hybrid search